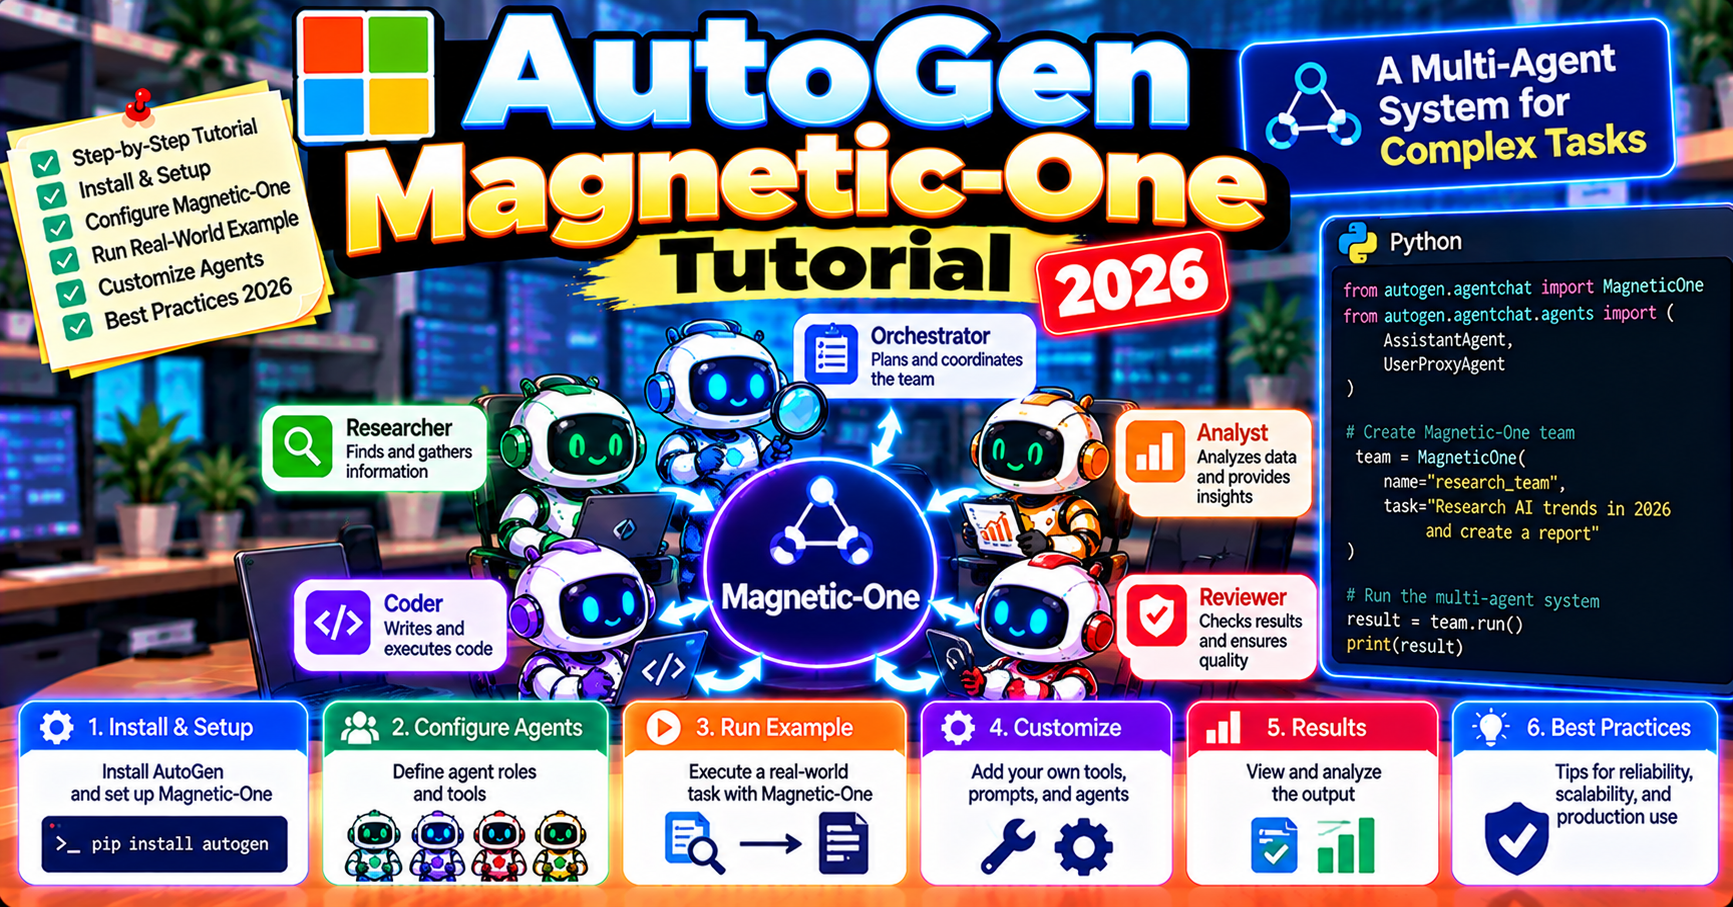
Magentic-One is Microsoft Research’s generalist multi-agent system for web and desktop tasks. Shipped in late 2024, matured through 2026, it composes 5 specialized agents (orchestrator, web surfer, file surfer, coder, computer terminal) using AutoGen primitives. The result: a working agent that browses the web, reads files, executes code, and takes screen actions to complete multi-step tasks like “research the top 3 cloud providers’ Kubernetes pricing and compile it into a spreadsheet.” This tutorial walks through installing Magentic-One, running your first task, and understanding when to use it vs. a custom agent.
What Magentic-One is
Magentic-One is a 5-agent system built on AutoGen. Each agent specializes:
- Orchestrator: plans the task, delegates to specialists, tracks progress, replans if needed
- WebSurfer: browses the web (Playwright-driven headless Chrome)
- FileSurfer: reads local files (PDFs, docs, spreadsheets, images)
- Coder: writes Python code to solve subproblems
- ComputerTerminal: executes shell commands and runs the Coder’s generated scripts
The orchestrator maintains a plan + progress ledger. It assigns subtasks to specialists, reads their outputs, updates the plan, and continues until the task is complete or it hits a stop condition. On the GAIA benchmark (general assistant tasks), Magentic-One achieved competitive scores against the best custom agent systems in 2024-2025.
Install Magentic-One
pip install "autogen-agentchat" "autogen-ext[magentic-one,openai]"

# Playwright browsers for WebSurfer
playwright install

# .env
OPENAI_API_KEY=sk-...
# Optional for isolated code execution (recommended):
DOCKER_HOST=unix:///var/run/docker.sock
Magentic-One ships inside autogen-ext. The magentic-one extra pulls Playwright + document parsers. For safe code execution, install Docker and point DOCKER_HOST at the daemon; otherwise code runs on your local machine (fine for trusted workloads, risky for untrusted ones).
Run your first Magentic-One task
import asyncio
from autogen_agentchat.ui import Console
from autogen_ext.models.openai import OpenAIChatCompletionClient
from autogen_ext.teams.magentic_one import MagenticOne

async def main():
    client = OpenAIChatCompletionClient(model="gpt-4o")
    m1 = MagenticOne(client=client)
    task = "Find the current pricing of GitHub Copilot Business and GitHub Copilot Enterprise, and tell me the price difference per user per month."
    await Console(m1.run_stream(task=task))

asyncio.run(main())
That is it. Magentic-One instantiates all 5 agents, the orchestrator plans the task, dispatches WebSurfer to github.com/features/copilot, parses the pricing page, and returns the answer. First run takes 1-3 minutes depending on network + model latency.
What tasks fit Magentic-One
Good fits:
- Web research tasks requiring navigation across multiple pages (“compare pricing for X, Y, Z on their sites”)
- Document extraction (“read these 10 PDF invoices and compile a spreadsheet of totals”)
- Mixed-modality tasks (“download this CSV, run analysis in Python, screenshot the chart”)
- Tasks requiring code execution to solve a specific calculation
- Prototyping an agent-for-X before deciding whether to build a custom narrow agent
Bad fits:
- High-volume production (overkill; use a custom narrow agent)
- Latency-sensitive tasks (5 agents means lots of LLM calls = slow)
- Tasks requiring strict compliance / auditability (the generalist orchestrator makes decisions you may not want to document to auditors)
- Tasks with sensitive data (code execution + web browsing increase attack surface)
Cost per task
Magentic-One is expensive because it uses multiple LLM calls per step. Realistic per-task cost on gpt-4o:
- Simple task (one web search, one answer): $0.15-$0.40
- Medium task (compare 3 sources, synthesize answer): $0.80-$2.00
- Complex task (download data, run analysis, generate chart): $3-$10
Mitigations:
- Use gpt-4o-mini for the orchestrator and specialists (cuts cost 5-10x with modest quality drop on easy tasks)
- Set
max_turnson the team to cap LLM calls - Reserve Magentic-One for genuinely complex tasks; use custom narrow agents for repetitive volume
Safety: code execution is powerful but dangerous
Magentic-One’s Coder and ComputerTerminal execute arbitrary Python and shell commands. In untrusted environments this is a security concern.
Recommended isolation:
- Docker container execution: set DOCKER_HOST so code runs in a container, not on the host. Default behavior if Docker is detected.
- Firejail / nsjail sandbox: for Linux hosts, add additional process isolation
- Network restrictions: deny the code-execution container outbound access to internal networks (block AWS metadata endpoint 169.254.169.254, block LAN ranges)
- Timeout caps: set max execution time per code block
- Never run untrusted user tasks: if the task specification comes from an external user, treat Magentic-One output as untrusted and sandbox heavily
Observability
Enable Console UI during development to see every agent’s actions in real time (await Console(m1.run_stream(task=task))). For production monitoring:
import agentops
agentops.init(os.environ["AGENTOPS_API_KEY"])
# ... Magentic-One execution auto-traces
AgentOps shows the full orchestrator plan, delegations, specialist outputs, and cost per step. Essential for debugging why a task failed.
Common Magentic-One pitfalls
- WebSurfer gets stuck on cookie banners / popups: known limitation. The Playwright screenshot + accessibility tree sometimes misses accept-cookies dialogs. Fix: for critical sites, add a custom WebSurfer subclass that auto-dismisses known popup patterns.
- Orchestrator over-plans simple tasks: for 1-step tasks, Magentic-One spends 3-5 LLM calls just planning. If your task is simple, do not use Magentic-One; call Claude or GPT-4o directly.
- FileSurfer PDF parsing limits: text-heavy PDFs work; image-heavy or scanned PDFs need OCR which FileSurfer does not run by default. Pre-process scanned docs with Tesseract or Google Document AI.
- Code execution hangs: Coder generates infinite loops occasionally. Set DOCKER container with timeout; kill after 60-120 seconds.
When to graduate from Magentic-One
Magentic-One is a generalist. If you find yourself:
- Running the same task shape hundreds of times per day
- Fighting the orchestrator’s generalist decisions
- Hitting cost ceilings
- Needing specific tools Magentic-One does not have
Build a custom narrow agent for that specific workflow. Faster, cheaper, more predictable. Magentic-One is a scaffolding tool and prototype system; production specialists outperform it on their specific tasks.
Common deployment patterns
Teams running Magentic-One in production usually land on one of three deployment shapes:
1. Interactive research tool. Analyst or researcher opens a chat UI, submits ad-hoc questions, Magentic-One runs for 1-5 minutes and returns findings with citations. Cost per query ~$1-5. Users accept the latency because the alternative is 30+ minutes of manual research. Think “ChatGPT with web browsing but more thorough.”
2. Batch job for recurring intelligence. Cron fires Magentic-One nightly with 50-200 queries (“latest pricing for X”, “latest version of Y”, “any news on Z”). Results feed a dashboard. Cost per batch ~$50-500. Easier to budget because queries are predictable; results arrive before the business day starts.
3. Human-in-the-loop reviewer. Magentic-One drafts a research brief; a human reviews before anything is published or acted on. The agent does 80% of the work; the human catches the 20% where it got things wrong. Cost per final brief ~$10-30 including human time; still much cheaper than fully-human research.
Monitoring + alerts in production
Even reliable agents fail unexpectedly in production. Three alert categories worth setting up:
- Cost spike alerts: if a single task runs over 2x expected cost, pause the pipeline and surface to a human. Catches runaway orchestrators that over-plan.
- Timeout alerts: cap individual task time (10 min typical). Timeouts mean the agent is stuck in a loop; investigate before continuing.
- Low-confidence outputs: parse the orchestrator’s final response for hedging language (“I was unable to”, “could not find”, “may not be accurate”) and route those to human review instead of auto-publishing.
Frequently Asked Questions
Official documentation
Does Magentic-One work with non-OpenAI models?
Yes. Replace the OpenAIChatCompletionClient with any autogen-ext client (AnthropicChatCompletionClient, OllamaChatCompletionClient). All 5 Magentic-One agents can share the same client or use different models each. Common pattern: Claude Opus 5.5 for orchestrator (hardest decisions), Claude Sonnet 5.5 for specialists.
Can I disable certain agents?
Yes. The MagenticOne constructor accepts an agents parameter. Pass only the agents you need (e.g., [WebSurfer] for web-only tasks, skip Coder + ComputerTerminal if you do not want code execution). Reduces attack surface and cost.
How does Magentic-One compare to AutoGen’s base multi-agent?
Magentic-One is a prebuilt specific team using AutoGen primitives. The base AutoGen lets you build custom teams for your workflow. Use Magentic-One as a template; use base AutoGen when your workflow has specific needs not covered by the 5-agent default.
Can I run Magentic-One in production?
Yes, with care. Isolate code execution in Docker, cap per-task cost, add timeouts, and expect occasional failures that require human escalation. For low-volume high-value tasks (research, document analysis, triage), Magentic-One is production-grade; for high-volume repetitive tasks, build a narrow custom agent.
What about data privacy and security?
Magentic-One sends task descriptions + web content + code execution results to your LLM provider. For sensitive data, use a self-hosted model (Ollama + Llama 3.3 70B) via the Ollama client. Enterprise Azure OpenAI customers can keep data within their Azure boundary.
Is Magentic-One actively maintained?
Yes. Microsoft Research continues to update it as part of the AutoGen ecosystem. Expect roughly quarterly releases with capability improvements. Follow the autogen-ext repo on GitHub for release notes.

Angel Jude Suarez
Full-Stack Developer at PIES IT Solution
Focuses on Python development, machine learning, and AI integration. Has built production AI systems including OpenAI Whisper integration for medical transcription and GPT-4o-powered diagnosis assistance. Strong background in pandas, scikit-learn, and TensorFlow.
Expertise: Python · PHP · Java · VB.NET · ASP.NET · Machine Learning · AI Integration · OpenCV · Django · CodeIgniter · View all posts by Angel Jude Suarez →